

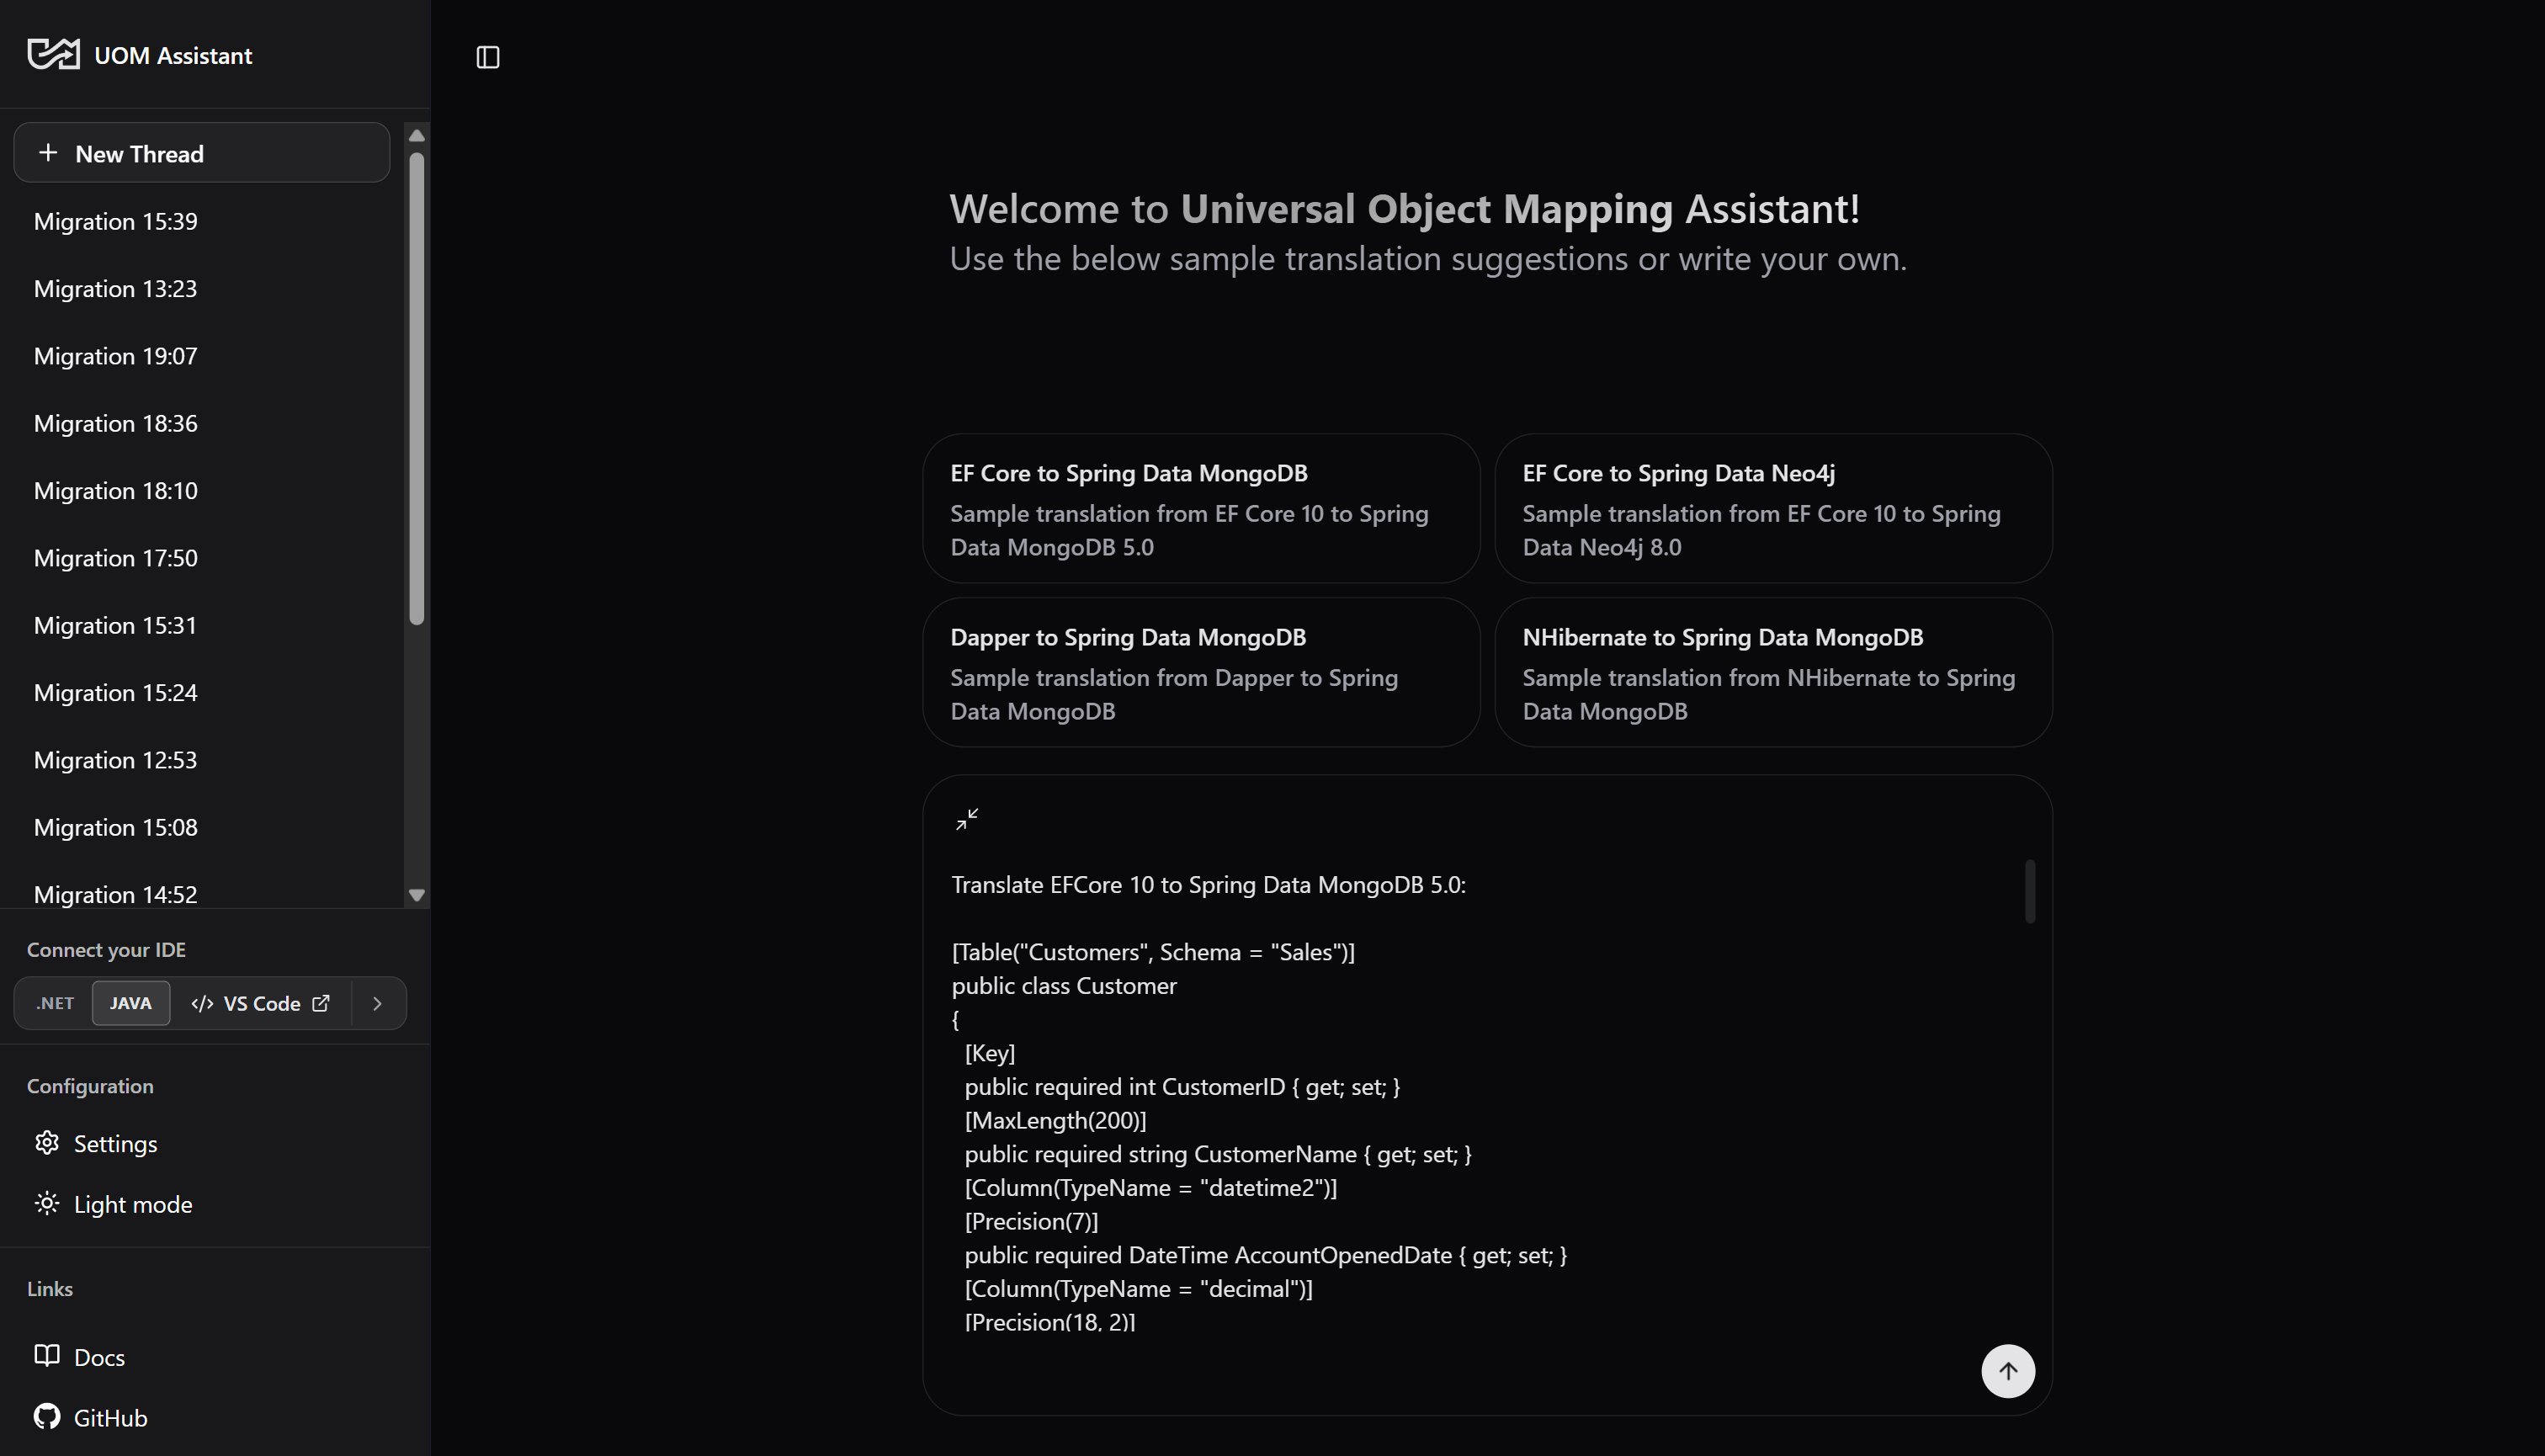
1. Project Background & Pedigree (ORMorpher)
UOM builds directly upon ORMorpher (originally developed by Milan Abrahám as part of his Master’s thesis, and later published in the IEEE/ACM International Conference on Automated Software Engineering - ASE 2025).- Legacy Rule Engine: ORMorpher established C# compiler-based heuristics using the Roslyn Scripting API to map SQL/LINQ queries to an Abstract Representation. It then used Integer Linear Programming (ILP) to dynamically benchmark and select optimal .NET frameworks based on runtime constraints.
- The LLM Advisor Extension: The UOM project extends this foundation by introducing an autonomous LLM Advisor to handle cross-paradigm schema and query transitions (Relational C# to Document/Graph Java). Rather than relying on rigid, hardcoded rules that struggle with heterogeneous schema mapping (like embedding tables vs. document nesting), UOM deploys an iterative, stateful LangGraph translation machine.
2. Platform Architecture & Data Flow
The complete UOM system coordinates containerized database engines, schema adapters, a Next.js user interface, and isolated Daytona compilation sandboxes:2.1 Component Matrix
- Frontend User Interface (frontend/uom-translator-ui): A modern Next.js App Router client utilizing assistant-ui library components. Styled with TailwindCSS and Shadcn/UI, it streams compilation diagnostic logs and DeepDiff result comparisons back to the user in real time.
- LLM Orchestrator (services/orchestrator): A Python-based service running a stateful LangGraph execution graph. Details of its state definitions, compiler nodes, and thread parameters are documented in the Orchestrator README.
- Validation Sandboxes: Ephemeral environment containers (.NET 10 SDK and Java OpenJDK 25) managed via Daytona to compile and execute generated code without risk to the host filesystem.
- Relational Source Database: A Microsoft SQL Server instance (
mssql_db) pre-loaded with the WideWorldImporters sample dataset.
3. Semi-Automatic ETL & Data Migration Pipelines
To validate query translations against real-world datasets, the target document (MongoDB) and graph (Neo4j) database engines must contain matching, logically equivalent data models. UOM defines a one-time, semi-automatic ETL process to map and migrate relational schemas:- Relational-to-Document Migration (MongoDB):
- Configured using MongoDB Relational Migrator (web dashboard at https://migrator.uom.dyn.cloud.e-infra.cz/).
- Users define how SQL columnar tables and primary/foreign key relationships map into MongoDB document collections, specifying document embedding patterns (e.g. embedding order items within parent orders) vs. referencing models.
- The migrator connects via JDBC and executes the ETL pipelines, populating the
uomdatabase in MongoDB.
- Relational-to-Graph Migration (Neo4j):
- Configured using the Neo4j ETL Tool and APOC plugins OR via the Neo4j ETL CLI for more control and to bypass UI issues. (NOTE: Neo4j ETL Tool UI is only available in Neo4j Desktop v1.6 and older)
- Maps relational tables to graph nodes, and foreign-key joins to node relationship labels (e.g.
(:Order)-[:CONTAINS]->(:Product)). - Populates the graph database, providing equivalent dataset structures prior to Cypher validation.
4. Setting It Up
Development requirements, a step-by-step local quick start (env files, container stack, ETL, Daytona key, LangGraph server, and Next.js frontend), and production deployment are all consolidated in one place:Getting Started
Requirements + the full local quick start, top to bottom.
DevOps & Deployment
Production Compose profiles, env configuration, and operations.
5. Subsystem Documentation Index
Review the following modular documentation files for detailed, verbose analyses of UOM’s backend orchestrator, Next.js frontend, and DevOps pipelines:5.1 UOM Orchestrator Backend Subsystem
System Architecture & LangGraph Nodes
Details graph logic, node transitions, and ReAct agent deprecations.
State Representation & Message Isolation
Explains the
translation_messages isolation layer and Context reflection.Daytona Sandbox Managers
Details baseline snapshot builds, exponential backoffs, and log streams.
Semantic Equivalence Algorithms
Reviews Base64 encoding, Maven executions, DeepDiff, and swapped sorting orders check logic.
DeepAgent & ACP Interfaces
Analyzes ACP session modes, local context inspection bash scripts, and CompositeBackend routing.
MCP Adapters & Toolbox Tools
Details SSE connections, MongoDB HTTP clients, and database safety fallback parameters.
5.2 UOM Advisor Frontend Dashboard
Frontend System Overview
Introduces the translation workspace features, suggestion engines, and workspace layout.
Frontend Architecture & Proxy Routing
Explains the API passthrough proxy, client-side SDK clients, state propagation context, and style utilities.
Frontend Runtime & Integration
Details configuration injection, sub-graph events, thread list synchronization adapters, and checkpoint tracking.
Frontend UI Component Specifications
Exhaustive details on Settings onboarding, Daytona remote IDE links, auto-scroll JSON visualizers, and streamdown markdown parsers.
Frontend Setup & Contribution Guidelines
Details dev requirements, production multi-stage Docker builds, and Biome coding standards.
User & Operator Guide
Explains how to start translation sessions, configure targets, diagnose build errors, and handle suspended human-in-the-loop checkpoints.
5.3 DevOps & Deployment Operations
DevOps Setup, Deployment & Operations
Exhaustive details on Docker Compose profiles, environment setups, sandbox timeouts, init/destroy scripts, and database initialization pipelines.
Acknowledgements
Part of thebenchmarks source code, including some workflows and diagrams, were developed by Milan Abrahám as part of his Master thesis titled Framework-Agnostic Query Adaptation: Ensuring SQL Compatibility Across .NET Database Frameworks. The thesis is available at http://hdl.handle.net/20.500.11956/203083, and the source code is available at https://github.com/milan252525/orm-convertor.